If you run A/B testing on real revenue flows, variance isn’t a stats problem. It’s a cash problem.
Every extra week you wait for confidence is a week you keep a worse checkout, a weaker onboarding, or a lower-priced plan. That slows Decision making, and it quietly taxes your growth strategy.
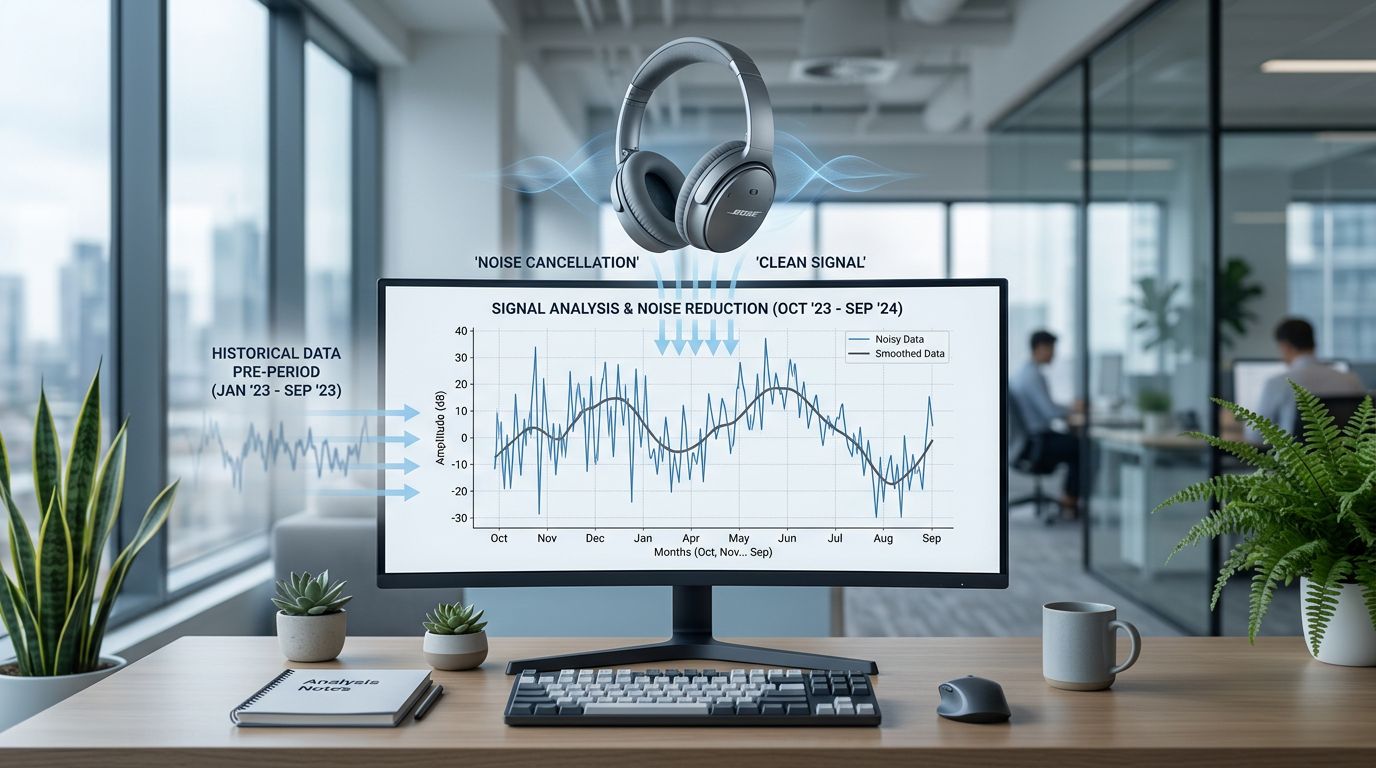
The CUPED method is one of the few techniques that can shorten that wait without changing the product or buying more traffic. It does it by using pre-period data (what users did before the experiment) to cancel out “who they are” noise. Think noise-canceling headphones for experimentation.
Why variance is expensive (and why CUPED pays for itself)
Most teams underestimate how often tests fail for boring reasons. Not because the idea was wrong, but because the metric was noisy.
Here’s the practical failure mode I see in startup growth all the time:
- You ship a pricing or paywall test.
- Your primary metric is purchase conversion or revenue per visitor.
- The result is directionally positive, but not conclusive.
- You either ship it anyway (risk) or wait (time).
That’s not a math debate. It’s behavioral science meeting messy reality. Some users were already “hot” buyers. Some were never going to convert. That mix can swing your metric more than your variant did.
CUPED reduces that swing by adjusting each user’s experiment outcome using what you already know about them from a pre-period. If a user was already a heavy buyer or a frequent engager, CUPED partially subtracts that predictable component. What’s left is closer to the treatment signal.
Financially, the payoff shows up in two places:
- Shorter time-to-decision: If variance drops, confidence intervals tighten, so you can reach a call sooner.
- Fewer wasted cycles: Less “inconclusive” means fewer reruns and fewer stakeholder battles.
If you’re planning test duration and minimum detectable effect, this pairs naturally with a tool like an A/B test sample size calculator. I still validate power the old-fashioned way, but I want the planning friction near zero.
For a solid product-oriented explanation of CUPED in plain terms, I’d also skim Statsig’s CUPED overview. Even if you don’t use their stack, the intuition maps well to most setups.
How the CUPED method works (without turning this into a stats lecture)

An AI-created infographic showing how CUPED uses pre-period data to reduce variance and narrow confidence intervals.
CUPED stands for Controlled Experiment Using Pre-Experiment Data. The idea is simple: if your outcome metric during the test is correlated with something you can measure before the test, you can reduce variance by controlling for it.
The standard adjustment looks like this:
Y* = Y − θ(X − X̄)
Yis the experiment-period outcome (for example, revenue per user, sessions, clicks, or conversion).Xis the pre-period covariate (the same metric, or something strongly related).θis estimated from historical or pre-period data.Y*is the adjusted outcome you analyze.
Why this works: randomization ensures treatment and control have the same distribution of “types” on average. Still, in a finite sample, you can get unlucky. CUPED uses each user’s own baseline to remove some of that luck.
A quick way to think about expected gains: if the correlation between X and Y is ρ, the variance reduction is often close to ρ². So a 0.5 correlation can cut variance by around 25%. A 0.7 correlation can cut it near 49%. That turns a long wait into a shorter one, especially on metrics like revenue where user heterogeneity dominates.
If your pre-period metric doesn’t predict your experiment metric, CUPED won’t save you. Correlation is the fuel.
One detail that matters in real life: your pre-period must not overlap the experiment period. Overlap can contaminate the adjustment and create bias. Many platforms now call this out explicitly, for example in Optimizely’s CUPED support guide.
How I decide whether to use CUPED in a real experiment
I don’t treat CUPED as “always on.” I treat it like any other analytics decision: it has assumptions, and it can backfire if you get lazy.
Step 1: Pick a pre-period covariate that matches user behavior
The safest default is the same metric in the pre-period. If you’re testing purchase conversion, use pre-period purchase conversion or pre-period purchase intent signals (like “started checkout”) if you lack purchases.
This is where product-led growth teams often have an advantage. You usually have rich engagement trails (activation events, retention, feature usage) that predict later conversion. Use them, but don’t get fancy too early.
A simple table I use when I’m pressure-testing a setup:
| Scenario | Pre-period data available? | Expected CUPED value | My call |
|---|---|---|---|
| Repeat users (SaaS app), same metric exists | Yes | High | Use CUPED |
| Repeat users, strong proxy exists | Yes | Medium | Try CUPED, validate on past tests |
| Mostly new users (SEO landing page) | No | Low | Skip CUPED |
| Metric changed definition recently | Risky | Unclear | Skip until stable |
If you want a deeper technical walk-through, Matteo Courthoud’s write-up is clear and grounded: variance reduction with CUPED.
Step 2: Check the “can this bias me?” traps
CUPED is variance reduction, not a permission slip to ignore rigor.
Common failure points:
- Instrumentation drift: If tracking changed between pre-period and experiment, you inject noise or bias.
- Non-stationary behavior: Seasonality and promos can weaken the pre to post link.
- One-time users: If most users are new, pre-period covariates are missing. Imputation can get weird fast.
- Metric manipulation: If your variant changes the meaning of the metric (for example, redefining “active”), CUPED can adjust the wrong thing.
Applied AI can help with covariate selection (finding predictors), but I don’t let a model pick covariates blindly. A covariate must make product sense. Otherwise you end up with brittle experiments that nobody trusts.
Step 3: Make the decision easy for stakeholders
Even if CUPED is statistically sound, your org still needs to act. I like to publish both views:
- Raw metric result (easy to understand)
- CUPED-adjusted result (more power)
Then I keep the decision rule consistent across tests. When I share outcomes, I want one link people can open and understand quickly, which is why I like having an A/B test reporting dashboard instead of rebuilding decks.
Finally, CUPED helps you decide faster, but it doesn’t tell you what to test next. After you bank a winner (or learn from a loss), I want the next bet to be tightly connected to what happened. That’s where a system for AI test iteration recommendations can help keep momentum without repeating old mistakes.
Short actionable takeaway
For your next experiment, do this before you launch:
- Choose a pre-period window (7 to 28 days) that does not overlap the test.
- Compute correlation between pre and post metric on historical data or a recent holdout.
- If correlation is below ~0.3, skip CUPED and fix the metric or hypothesis.
- If correlation is above ~0.5, use CUPED and plan for a shorter runtime, but still enforce guardrails (SRM checks, no peeking rules).
Conclusion
When time is the constraint, not ideas, the CUPED method is one of the cleanest ways to speed up A/B testing without lowering standards. It works best when user history predicts outcomes, and it fails when you don’t have stable pre-period data.
If you’re under pressure, my advice is simple: use CUPED when it meaningfully tightens confidence intervals, and ignore it when the covariate is weak or messy. That’s how you protect decision quality while still moving fast on conversion and product changes that drive startup growth.
Leave a Reply